Apple may be weighing a return to selling servers, this time aimed squarely at the AI market rather than at the rack room nostalgia crowd. The reported concept is an externally sold system built around future “M8” series processors, with Nvidia’s NVLink Fusion under consideration as the technology used to connect those chips.
There is a giant asterisk attached to every exciting noun in that sentence. The server itself is not final, an Nvidia arrangement is not final, and the prospective timing—reported as 2029—is not a promise. The project could still be canceled. But the direction is notable: Apple is reportedly looking beyond putting its silicon in individual Macs and toward supplying the sort of shared, on-premises AI infrastructure that companies can operate themselves.
For gaming and technology audiences, the useful way to read this is not “an Apple box will suddenly replace every AI machine.” It is that Apple appears to be considering where its chips fit when AI workloads stop being a single-user task and become a many-machine, many-customer operation. The difficult part is no longer merely making a fast processor. It is making several processors communicate fast enough, reliably enough, and cheaply enough that the overall system is worth buying.
A potential return after Xserve
Apple ended its previous Xserve business in 2011. The reported M8-based system would therefore mark a potential return to a product category it exited long ago, though it would be built for a very different job.
The intended buyers are reportedly businesses that want to run AI models on equipment they own. That distinction matters. Rather than relying entirely on remotely hosted computing, an organization could keep the hardware in its own facilities and use it for its own workloads. The reported emphasis is inference: the process of using an already trained model to produce an answer, response, classification, or other output.
Inference is distinct from training. Training is the process through which a model learns from data; inference is what happens afterward, when someone asks it to do something. In plain terms, training is the long, expensive study session, while inference is the moment the model has to answer the question without looking panicked at the clock.
That focus would make practical sense for businesses deploying models internally. They may care less about building a model from scratch and more about running one consistently for staff, customers, or internal tools. Apple already has an example of server-side AI infrastructure in Private Cloud Compute, which handles Apple Intelligence requests that require processing beyond the user’s device.
Private Cloud Compute is not presently an outside-customer server product. Partners have reportedly requested access to those servers, and Apple has declined. A separate commercial system would therefore be a significant change in how Apple approaches its AI infrastructure—if it happens.
Why Nvidia networking is central to the report
The most consequential reported ingredient is not necessarily the M8 branding. It is NVLink Fusion, Nvidia’s hardware-and-software platform for moving data between chips.
In an AI server, several processors must often work on the same task. If they cannot exchange information quickly, the system can spend too much time waiting. That bottleneck can undermine the benefit of adding more compute in the first place. Think of it less as adding more lanes to a highway and more as ensuring that all those lanes actually meet at an exit rather than dumping traffic into a hedge.
Apple’s existing inter-chip connections reportedly face cost and speed issues when scaled for this sort of server ambition. NVLink Fusion is being considered as a potential solution. It could enable Apple to link M8 processors in a larger system without making Apple dependent on Nvidia processors themselves.
This is an important technical distinction. Nvidia is widely associated with the chips powering AI systems, but the reported Apple concept would use Nvidia networking technology around Apple chips. NVLink Fusion gives Nvidia a way to provide the connective tissue to companies designing alternative processors. In that model, Nvidia can participate in AI infrastructure even when a customer is not choosing Nvidia compute chips for every role.
That creates an unusual but logical overlap of interests. An Apple server could compete with some Nvidia-based AI systems, while Nvidia could still benefit by supplying a crucial part of the architecture. Competition and partnership are not opposites in infrastructure; sometimes they are simply different rows in the same exceptionally expensive spreadsheet.
Apple’s AI hardware question is bigger than a single chip
Apple hardware has reportedly attracted growing interest from AI businesses, including bulk purchases of Mac mini and Mac Studio systems. Those machines can offer a workable route for organizations wanting Apple silicon in their compute setups. Yet assembling large quantities of small computers is not automatically the same thing as buying a purpose-built server platform.
A server product intended for serious business use needs more than processing power. It needs a coherent way to connect chips, deploy software, manage workloads, support customers, and give developers confidence that the platform will remain useful over time. The report says Apple still needs stronger enterprise support and more AI-developer resources, including further investment in MLX.
MLX is Apple’s machine-learning framework referenced in the report. A framework is the set of software tools and foundations developers use to build, adapt, and run machine-learning work. Hardware can be impressive on a specifications sheet, but developers need software that lets them use that hardware without treating every project like an archaeological dig.
This is why the reported effort should not be reduced to a question of whether an M8 chip is fast. Enterprise buyers generally need answers about software workflows, deployment, support, and the relationship between one server and a much larger environment. The report identifies these areas as challenges still facing the project.
A changing Apple-Nvidia relationship
The reported conversations also point to a closer working relationship between Apple and Nvidia after longstanding disputes between the companies. Apple has already announced plans to extend Private Cloud Compute to Google Cloud using Nvidia GPUs. The companies have reportedly explored further AI collaboration, including potential use of Nvidia’s open-source models.
That does not establish that an Apple-Nvidia server deal will happen. It does, however, show that the two companies have reasons to work together in areas where their technologies complement one another. Apple brings its own processors and existing Private Cloud Compute infrastructure; Nvidia brings GPU and networking expertise that spans the broader AI ecosystem.
For Apple, a partnership could address a specific scaling problem without abandoning the company’s own silicon strategy. For Nvidia, NVLink Fusion could broaden its role among companies producing non-Nvidia processors. It is a potentially mutually useful arrangement precisely because neither side has to stop pursuing its own hardware ambitions.
What this could mean for developers and businesses
Nothing is available to buy from this report, and no one should plan an infrastructure refresh around a machine that may not exist. Still, the reported proposal highlights a few concrete questions that developers and organizations can watch as AI hardware evolves.
- Inference deployment: Businesses that want to operate AI models on their own equipment may have more hardware approaches to assess if Apple enters this market.
- Scaling: The performance of a multi-chip system depends heavily on how its components share data. Interconnect technology can be as meaningful as the processors on the board.
- Software maturity: MLX investment and broader developer tooling would be essential to a credible Apple enterprise AI platform.
- Support expectations: A commercial server needs business-facing support and operational resources, not simply a powerful chip inside attractive industrial design.
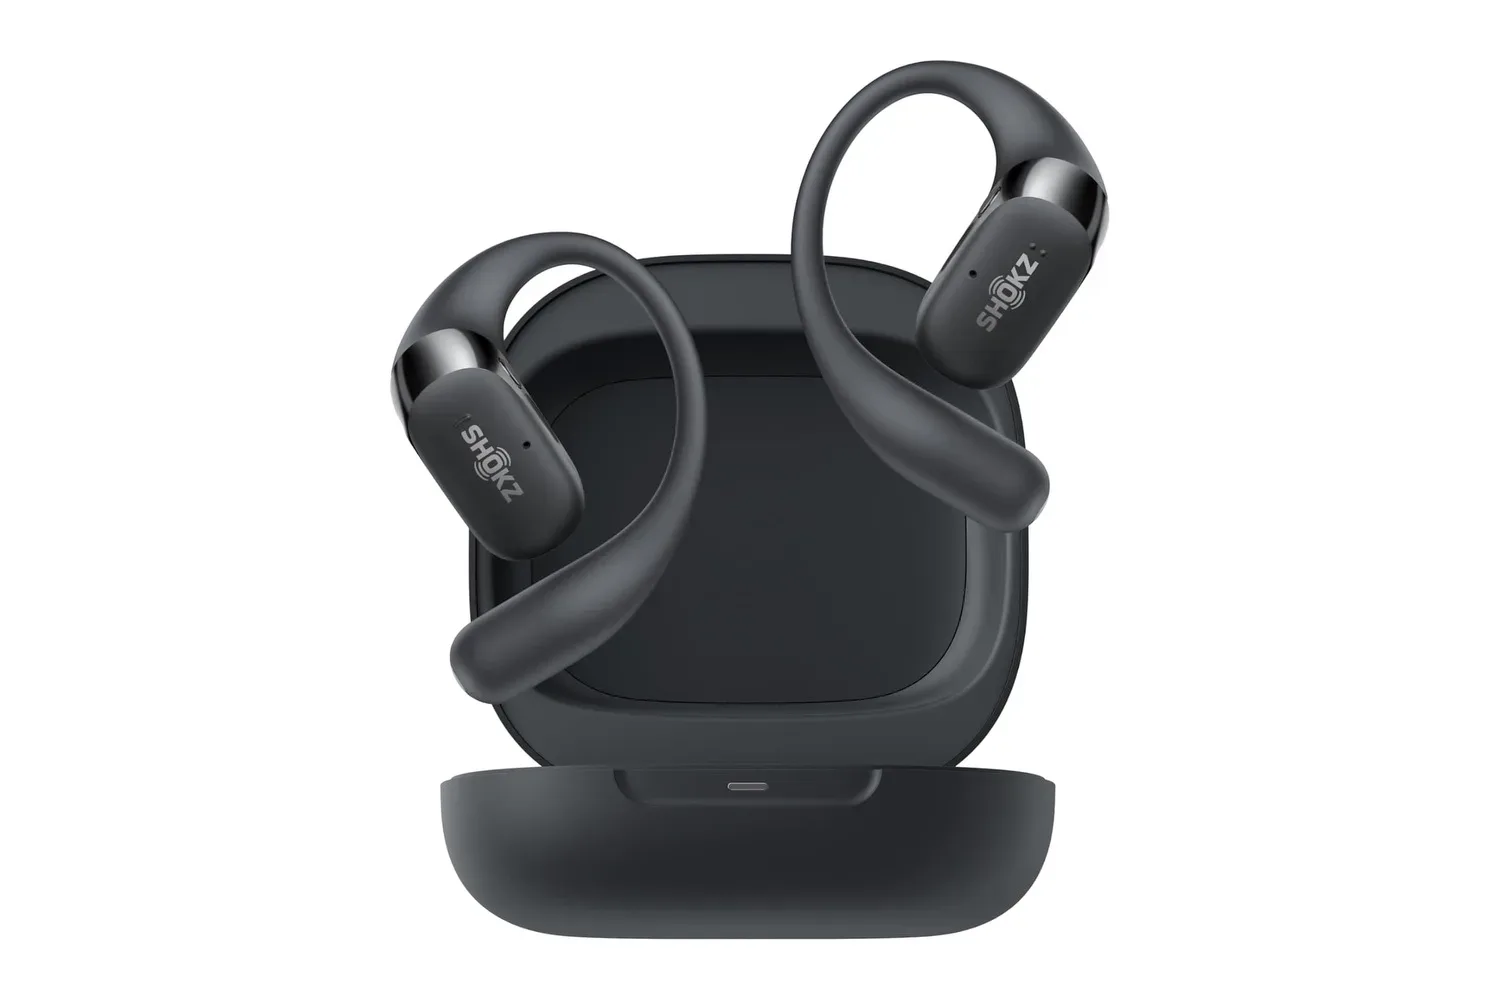
The distinction between enterprise infrastructure and Apple’s familiar consumer technology is worth keeping clear. A product like the OpenFit 2 earbuds is judged by day-to-day convenience, comfort, and battery considerations; a server platform lives or dies by sustained workloads, software compatibility, connectivity, and support. Both can involve clever hardware. Only one is expected to spend its working life negotiating with racks of equipment and a data center’s cooling plan.
Important caveats: this is a reported project, not a roadmap
The most responsible interpretation is cautious. The reported release window is 2029, several years away, and the plan could be dropped. There are no confirmed specifications, customer commitments, pricing details, configurations, or finalized Nvidia agreement in the information available here.
The “M8” designation should similarly be treated as part of the reported plan, not as a confirmed product announcement. Apple’s existing work on Private Cloud Compute and the reported demand for Mac mini and Mac Studio systems provide context for why such a project may be under consideration, but they do not guarantee that Apple will bring a standalone AI server to market.
Still, the report is meaningful because it frames Apple’s next AI-hardware question in unusually direct terms: can the company turn its silicon strengths into a scalable product for organizations that need to run models themselves? Connecting M8 chips with Nvidia networking could be one answer. Whether Apple commits to that answer—or decides the server market is a boss fight better left unqueued—remains unresolved.